Final-year Engineering Physics student at Delhi Technological University with a Minor in Computer Science. Focused on backend and agentic GenAI systems that hold up in production — LLM gateways with cost and safety guardrails, multi-agent LangGraph pipelines with MCP tool-calling agents, and RAG systems backed by measured evaluation. Experienced in FastAPI, Docker, AWS, LangChain/LangGraph, Redis, and deploying scalable inference pipelines end-to-end.
Mentored students on academics and career planning.
Guided 4 students through one-on-one mentoring.
Project 1 of 3
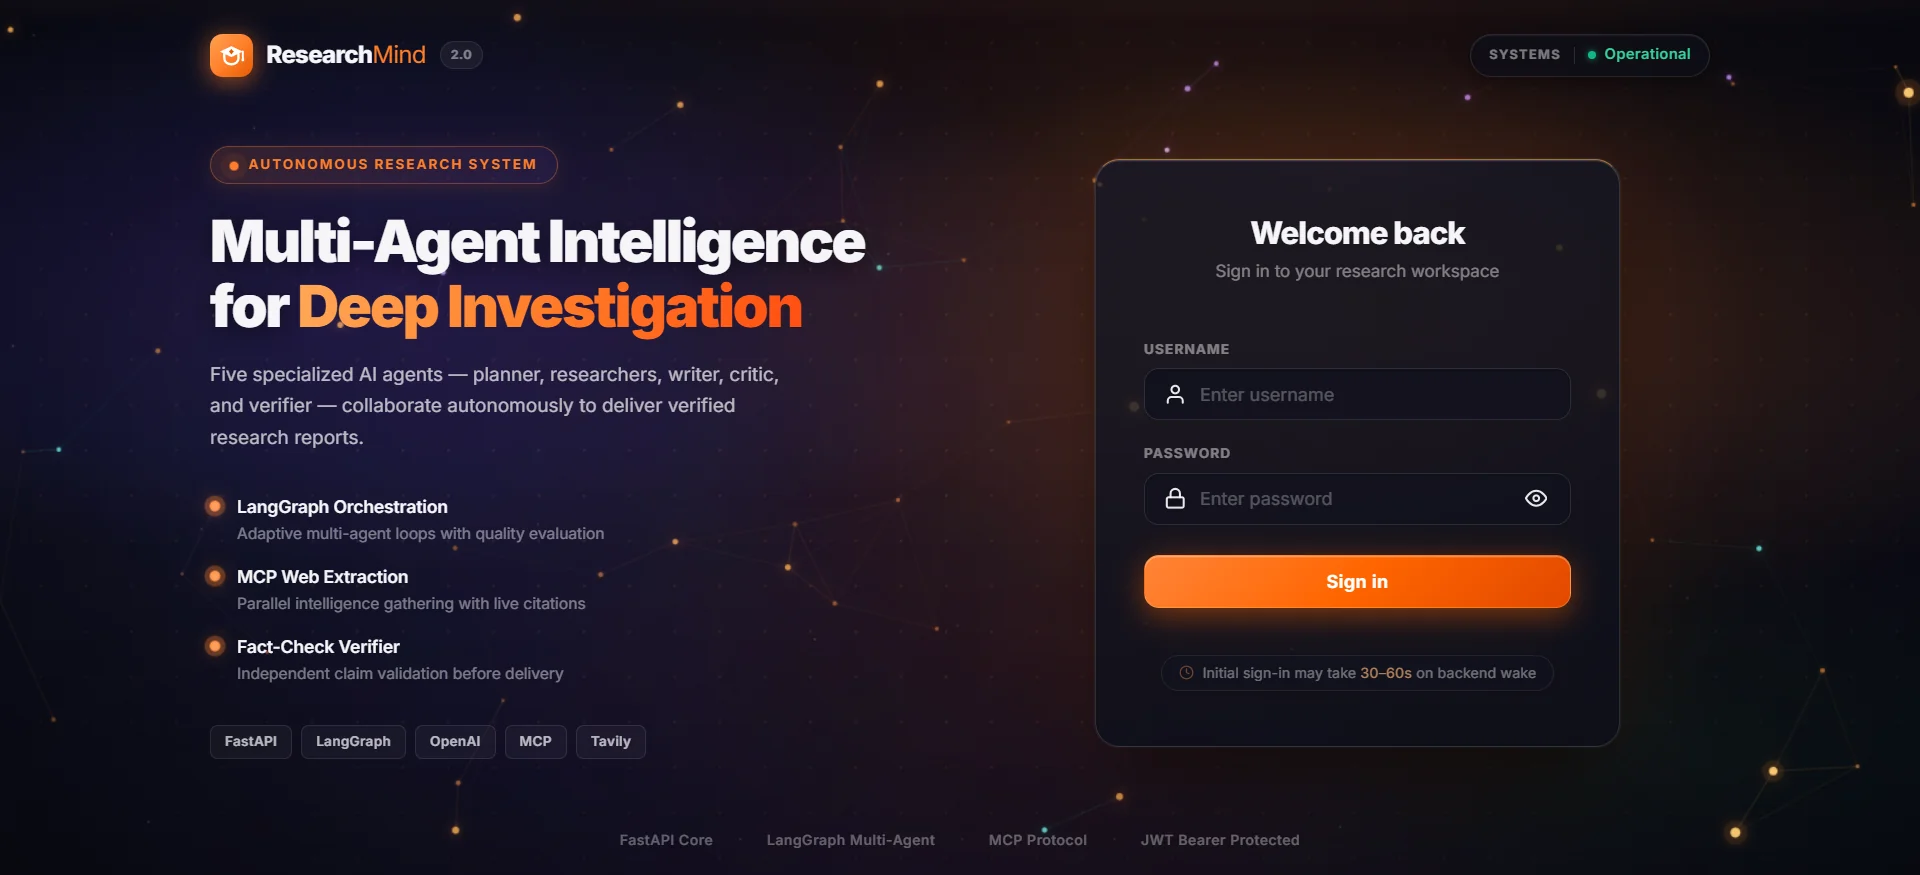
ResearchMind — Multi-Agent AI Research System
FastAPI
LangGraph
MCP
OpenAI API
JWT
Prometheus
Docker
Multi-agent research pipeline orchestrated with LangGraph — parallel MCP tool-calling agents for research and independent, tool-verified claim checking.
Key Highlights & Architecture
Orchestrated a LangGraph StateGraph pipeline — plan, parallel research, write, critique, verify — with conditional routing driven by structured LLM output.
Built a standalone MCP tool server (FastMCP) exposing web search, page scraping, arXiv search, and a sandboxed calculator to independent tool-calling agents.
Parallelized sub-question research via LangGraph's Send API, fanning out concurrent researcher agents that each independently choose which MCP tools to call.
Designed a dynamic planner that scales sub-question count with topic complexity and can return a clarifying question instead of researching an ambiguous topic outright.
Implemented an iterative critic loop with a structured score + issue-type verdict, routing failures back to the planner or writer under an iteration cap and token budget.
Built an independent verifier agent that re-investigates a report's most load-bearing claims against fresh sources via its own tool calls, then returns a per-claim yes/no/partial verdict.
Secured the API with JWT auth and instrumented every pipeline stage with per-step Prometheus histograms plus request-ID-tagged structured JSON logging.
Deployed FastMCP and FastAPI as a single unified container via a custom entrypoint process supervisor, backed by an async pytest suite with a fully mocked pipeline.
Preview & Interface
‹›
https://researchmind.madhavmakwana.dev
Click to enlarge
ResearchMind Dashboard
Project 2 of 3
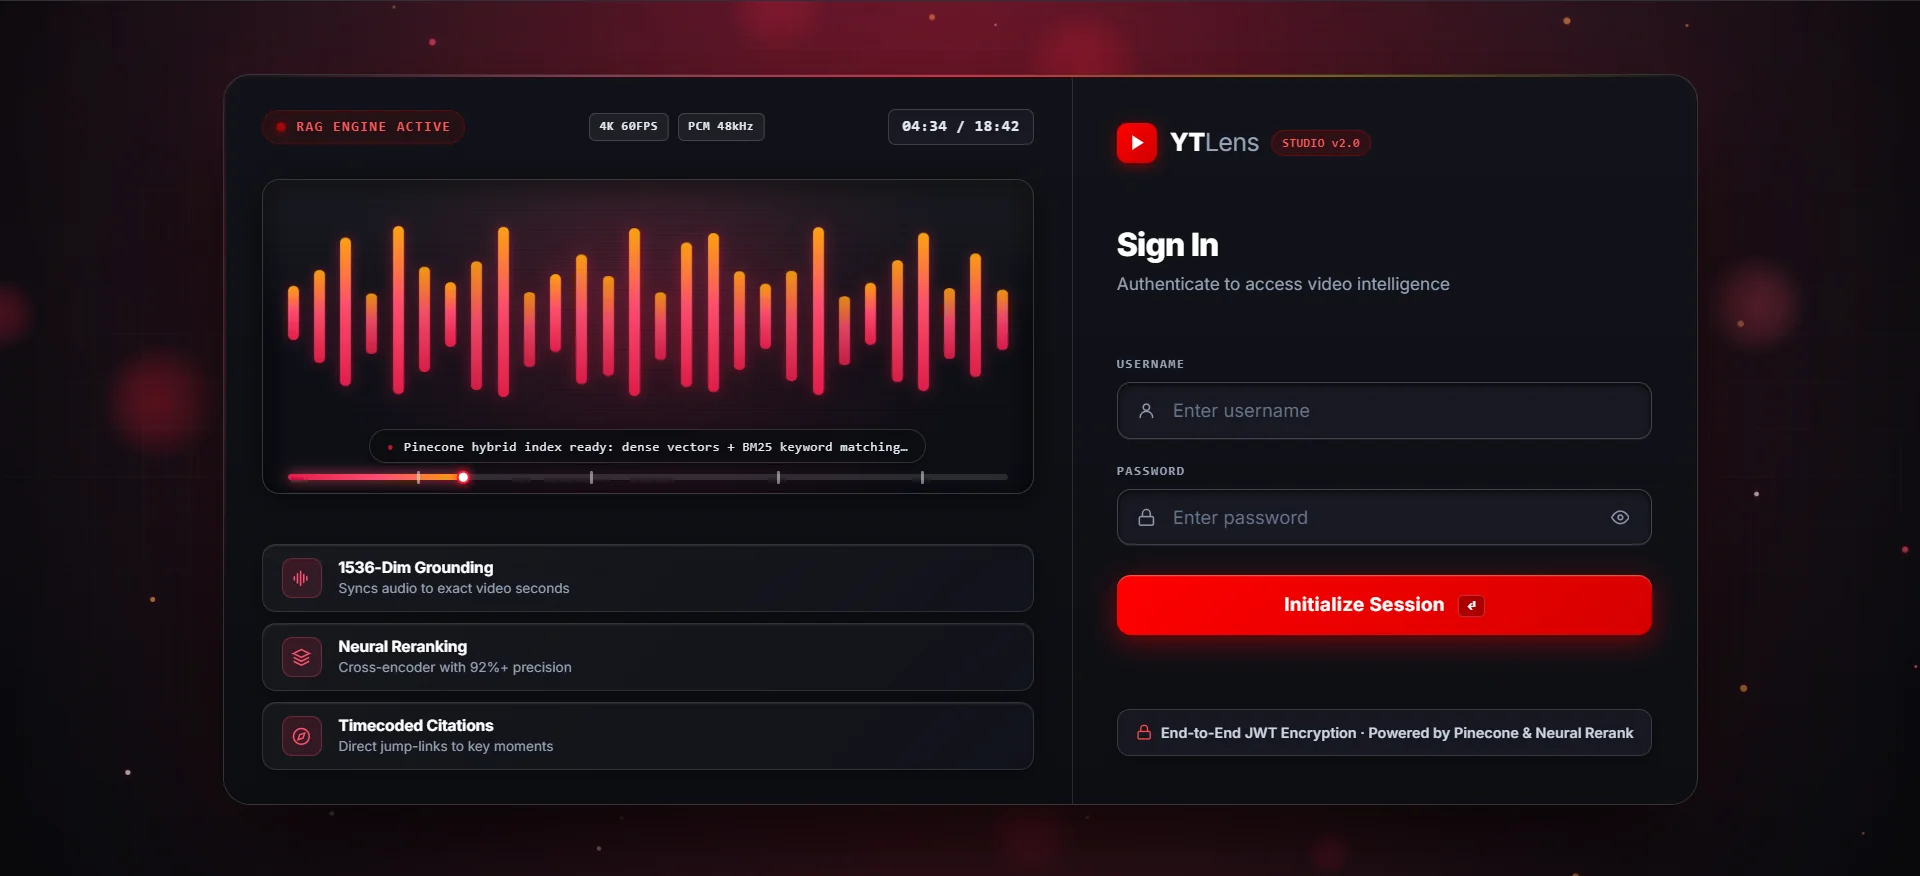
YTLens — RAG-Powered YouTube Q&A System
FastAPI
LangChain
Pinecone
OpenAI API
Cross-Encoder Reranking
JWT
Evaluation-driven RAG system over YouTube transcripts — cross-encoder reranking validated against a labeled retrieval benchmark, not assumed.
Key Highlights & Architecture
Built an end-to-end RAG pipeline — sentence-boundary-aware chunking, text-embedding-3-small embeddings, and namespaced Pinecone storage that survives backend restarts and redeploys.
Namespaced the vector store per video ID so retrieval for one video can never leak chunks from another, with the namespace doubling as an already-processed check.
Layered BAAI/bge-reranker-base cross-encoder reranking on top of dense retrieval, validating the choice against a labeled evaluation set rather than assuming it would help.
Built a 25-question labeled retrieval evaluation harness across 4 configurations — found hybrid BM25+dense fusion underperformed dense-only at this corpus scale, while reranking cut top-3 retrieval misses by 33%.
Designed a two-layer transcript fetch strategy with graceful degradation — direct fetch, then a residential proxy pass with a hard 3-second OS-level timeout overriding the library's own retry logic — before falling back to manual paste.
Made the chat model swappable via a single environment variable between OpenAI and free Hugging Face inference models, enabling zero-cost testing without touching pipeline code.
Streamed LLM responses token-by-token over Server-Sent Events so answers render progressively instead of blocking on full generation.
Secured the API with JWT auth and bcrypt-hashed passwords, with the admin user auto-reseeded on startup to survive Render's ephemeral filesystem wipes on redeploy.
Preview & Interface
‹›
https://ytlens.madhavmakwana.dev
Click to enlarge
YTLens Interface
Project 3 of 3
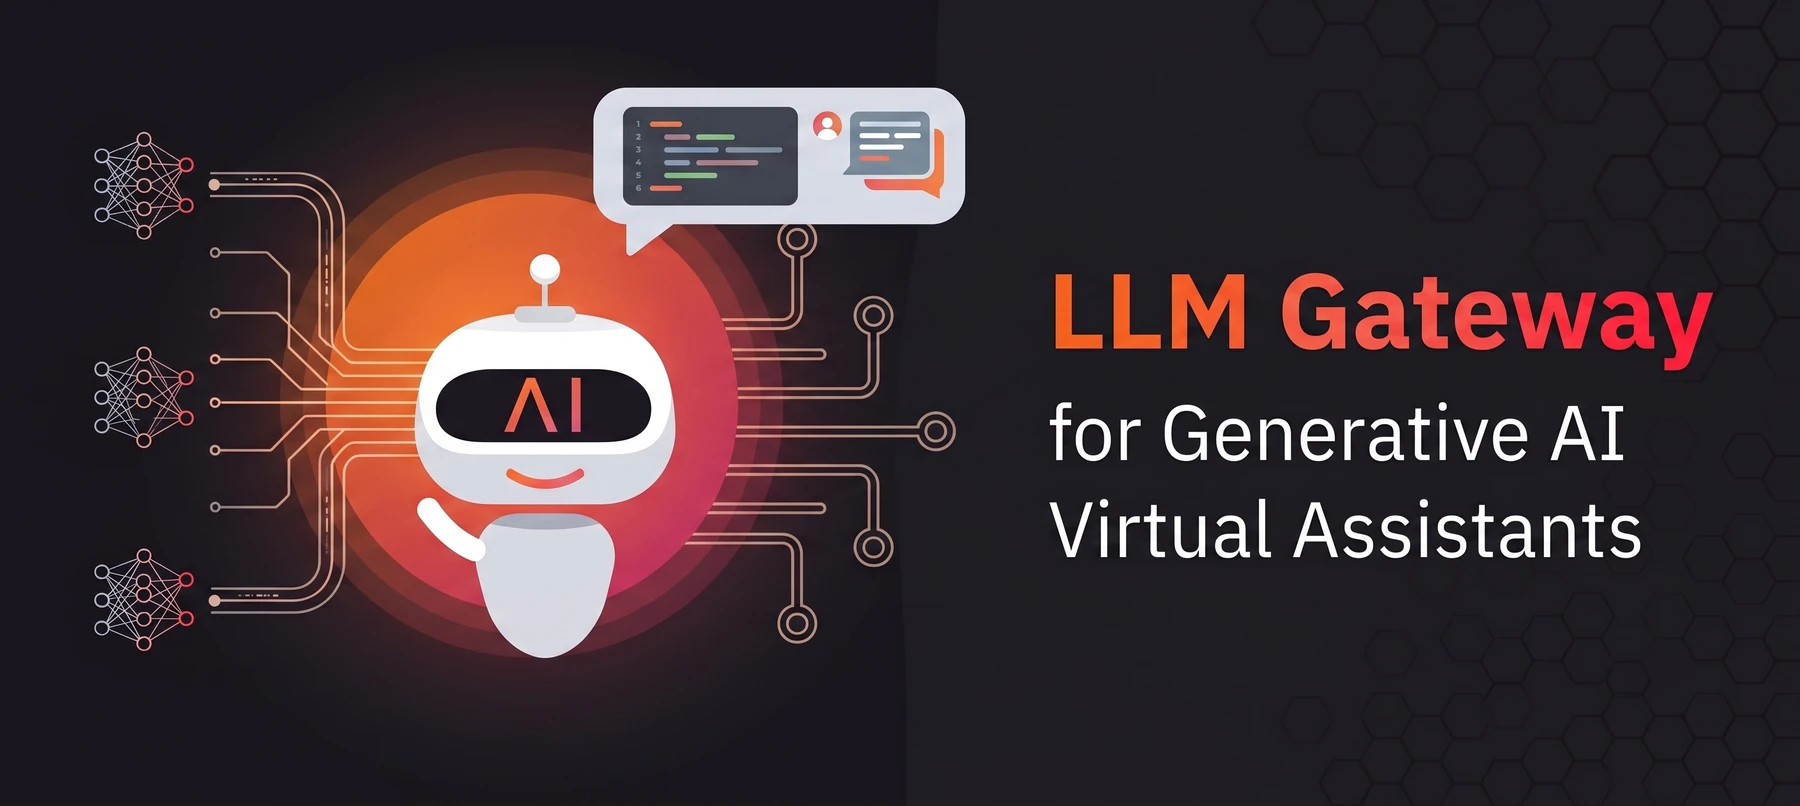
LLM Gateway — Secure, Cost-Aware Routing Proxy for LLM APIs
FastAPI
Redis
FAISS
Docker
AWS EC2
Prometheus
Grafana
pytest
Production-grade LLM gateway with circuit-breaker routing, dual-layer caching, prompt injection defense, and per-key budget enforcement — deployed to AWS EC2.
Key Highlights & Architecture
Architected an OpenAI-compatible gateway (/v1/chat/completions) with circuit-breaker routing across Groq and OpenAI, auto-failing over on timeout or provider error.
Designed a hand-rolled closed/open/half-open circuit breaker that skips known-bad providers until a recovery timeout elapses, avoiding wasted calls to a failing provider.
Built dual-layer caching — Redis exact-match plus FAISS-backed semantic similarity — to short-circuit both identical and near-duplicate prompts before they hit a model.
Implemented embedding-similarity prompt injection/jailbreak detection that screens and blocks adversarial requests pre-inference, with audit logging of block reasons.
Built a per-API-key token/cost ledger enforcing hard budget caps, returning 429 on overrun to guarantee spend never exceeds a configured limit.
Kept ledger writes, cache writes, and metric recording off the synchronous response path via background tasks to minimize response latency.
Instrumented the full stack with Prometheus (custom cache/injection/provider metrics plus auto-instrumented HTTP metrics) and a provisioned, zero-touch Grafana dashboard.
Wrote a pytest suite with a FakeProvider and fakeredis achieving full pipeline coverage — routing/fallback, breaker state transitions, caching, injection detection, and billing — with zero real API spend.
Preview & Interface
‹›
https://github.com/Maddy-MM/llm-gateway
Click to enlarge
LLM Gateway Architecture
Project Directory
Other Projects Archive
A collection of machine learning APIs, NLP systems, and analytical applications.
Car Price Prediction API
FastAPI
Redis
JWT
Prometheus
Grafana
Production-grade ML API for real-time vehicle price prediction.
Built a FastAPI inference service serving real-time price predictions.
Integrated Redis caching to eliminate redundant inference calls.
Enforced JWT + API key auth with Prometheus/Grafana observability.